A few years ago, picking an AI model felt like choosing a house. You researched, committed, and expected to live there for a while. Today it looks more like renting a hotel room: you check in on launch day, and a month later you are packing for the next one.
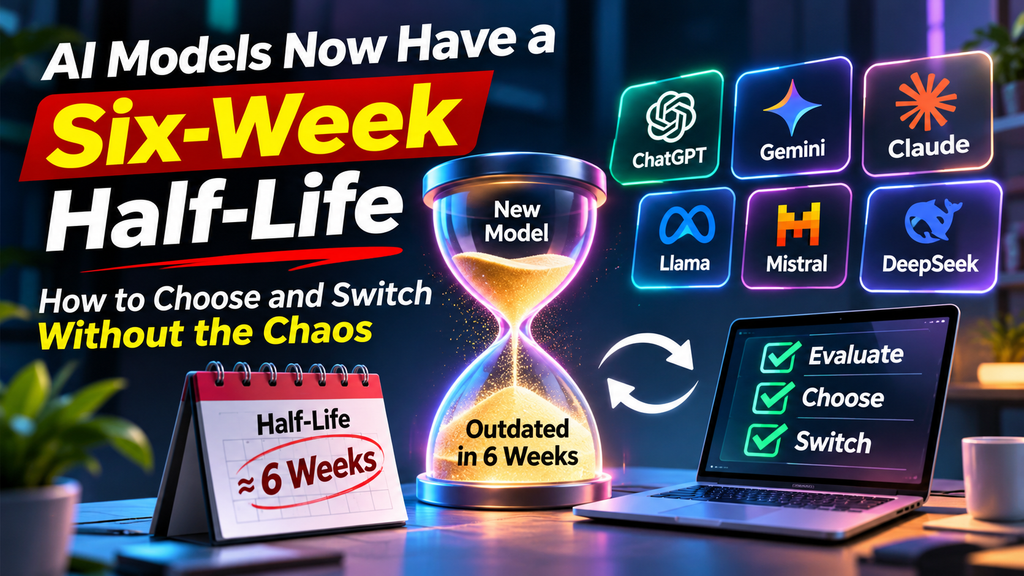
That is the picture painted by Vercel’s AI Gateway Production Index for November 2026. Looking at real traffic from teams building with AI, Vercel found that a typical new model peaks within about four weeks of release, and that usage fades quickly once the next model arrives. The company describes this as a “half-life” of roughly six weeks.
For developers, startups, and any business building on AI, this changes the question. It is no longer just “Which model is best?” but “How do we build so that switching is cheap, safe, and boring?” This guide explains what the data shows and gives you a practical, step-by-step approach to stay flexible.
What the Vercel Data Actually Shows
Vercel analyzed token transactions flowing through its AI Gateway, which lets developers call many different models through one interface. According to coverage of the report, several patterns stand out:
- Fast adoption: Teams start using new models within days of release.
- Short attention span: Paid teams tend to stick with a new model for around four weeks on average before moving on.
- Young traffic: Most AI traffic runs on models less than two months old. By September, close to 17 percent of usage was on models available for under two weeks.
- Multi-model habits: Many teams use several models at once, so percentages across models add up to more than 100 percent.
- Rising media models: About one in six AI development teams now uses a video model, up from 10 percent in earlier months, and image generation spend also grew.
The report also said Anthropic’s Claude Opus 5.5 was the top model by spend in its first full month after its September 22 launch, and that Anthropic models led the list of most widely used paid models. Keep in mind that this data comes from one platform’s customers, who skew toward developers building web apps, so it may not describe every industry.
Why Teams Switch So Quickly
There are three simple reasons.
- Switching is easy. In many code editors and AI tools, changing a model is a dropdown or a single configuration line.
- Competition is intense. Labs release new versions often, each claiming better reasoning, lower cost, or faster speed.
- Fear of falling behind. Teams building agents and coding assistants worry that rivals using a better model will ship better products.
The risk is that chasing every release creates its own problems: inconsistent output, broken prompts, surprise bills, and no clear way to know whether the new model is actually better for your task.
Step 1: Separate Your App From Any One Model
The most important design choice is to avoid hard-coding a model name throughout your code.
Use a Single Configuration Point
Store the model name in one place, such as an environment variable or config file:
PRIMARY_MODEL=provider-a/model-x
FALLBACK_MODEL=provider-b/model-y
Your application reads these values at runtime. Changing models then becomes a config change rather than a code rewrite.
Consider an AI Gateway or Abstraction Layer
A gateway gives you one interface for many providers and often adds logging, rate limiting, and cost tracking. Vercel’s own gateway is one example, and other vendors and open-source tools offer similar features. The key idea is that your app talks to a stable interface, while models change behind it.
Step 2: Build a Small Evaluation Set
Benchmarks and launch-day hype tell you how a model performs on someone else’s tests. To know whether a model is right for you, test your own work.
- Collect 20 to 50 real examples of tasks your product handles, such as support questions, summaries, code fixes, or data extraction.
- Write down what a good answer looks like for each one. For structured tasks, this can be an exact expected output. For open-ended tasks, use a short checklist.
- Run every candidate model on the same set with the same prompts.
- Score the results for accuracy, tone, format, speed, and cost.
- Repeat whenever you consider switching.
This takes a few hours to set up and can save weeks of guessing. Even a spreadsheet works for a first version.
A Simple Scoring Example
Suppose you run an email-summarizing feature. Test three models on 30 emails and score each summary from 1 to 5 for accuracy and brevity, then record the cost per 1,000 summaries. If Model B scores almost the same as Model A but costs half as much, you have a clear, evidence-based reason to switch.
Step 3: Match the Model to the Task
The newest or most expensive model is not automatically the right choice. Many teams use a tiered approach:
- Small, fast models for simple, high-volume jobs such as classification, tagging, or short replies.
- Mid-range models for everyday writing, summarizing, and coding help.
- Top-tier models for complex reasoning, long documents, and difficult agent tasks.
The usage data supports this idea. Smaller and mid-sized models appear alongside flagship models in the most-used list, which suggests many teams mix tiers to balance quality and cost.
Step 4: Roll Out Changes Gradually
Treat a model switch like any other production change.
- Test offline on your evaluation set.
- Send a small share of traffic, perhaps 5 to 10 percent, to the new model.
- Compare results against the current model using the same metrics.
- Increase traffic in steps if quality holds.
- Keep a one-click rollback to the previous model.
Pin specific model versions where the provider allows it, so a silent update does not change your product’s behavior overnight.
Step 5: Keep Your Prompts Portable
Prompts that work well on one model can behave differently on another.
- Write clear instructions and avoid tricks that depend on one model’s quirks.
- Keep prompts in version control, separate from application logic.
- Use structured output formats, such as JSON with a defined schema, so downstream code does not break when wording changes.
- Re-test prompts after every model change.
Step 6: Watch Costs and Plan for Failures
Fast switching can quietly inflate your bill if a new model uses more tokens or costs more per request.
- Track cost per task, not just cost per token.
- Set budgets and alerts with your provider or gateway.
- Configure a fallback model so your app keeps working if one provider has an outage, which, as recent cloud incidents show, can happen to anyone.
- Track deprecation dates. Providers retire older models, and you do not want to find out on the last day.
When Not to Switch
Staying put is sometimes the smarter move. Consider waiting if:
- Your current model meets your quality and cost goals.
- The new model has not been tested on your tasks.
- A switch would require major prompt rewrites with unclear benefit.
- Your product is in a regulated or high-risk area where changes need formal review.
A good rule is to switch when evidence says it helps you, not simply because something new exists.
Frequently Asked Questions
What does “AI model half-life” mean?
It is a way of describing how quickly attention and usage drop after a model launches. Vercel’s data suggests usage peaks within about four weeks and declines over roughly six weeks as teams move to newer options.
Should I always use the newest model?
No. Newer models are often better, but they can cost more, behave differently, or perform worse on your specific tasks. Test first.
How many models should my team use?
Most teams benefit from two or three: a cheap, fast model for simple tasks, a strong general model for everyday work, and a fallback from a different provider.
Do I need an AI gateway?
Not necessarily, but it helps. If you only use one model in a small project, a config file may be enough. Teams with several models or providers usually benefit from a gateway’s logging and cost controls.
Is this trend only relevant to developers?
It matters most for people building AI products, but business users are affected too. The tools you rely on may change their underlying models, so ask vendors how they test and announce those changes.
Conclusion
The six-week half-life is a sign of a fast-moving market, not a reason to panic. You do not need to chase every release. Keep your model choice in one place, build a small evaluation set from your real work, roll out changes gradually, and always keep a fallback ready. Do that, and the next big model launch becomes an opportunity to test and improve, not a scramble to rewrite your product.